ai observability articles
10 posts from the Atatus blog.
- alternatives
Dash0 Agent0 Alternatives: 5 Observability Platforms Compared
Dash0 Agent0 has real limits: OTel-only ingestion, usage-based billing, and a newer ecosystem. See how Atatus, Datadog, New Relic, Dynatrace, and SigNoz stack up on pricing, OTel support, and free trials.
- Observability
How to Choose an Observability Platform: A Growth-Stage Framework
A practical framework for choosing an observability platform as you scale like maturity levels, growth-stage requirements, hidden costs, and a buyer's evaluation checklist.
- GCP Monitoring
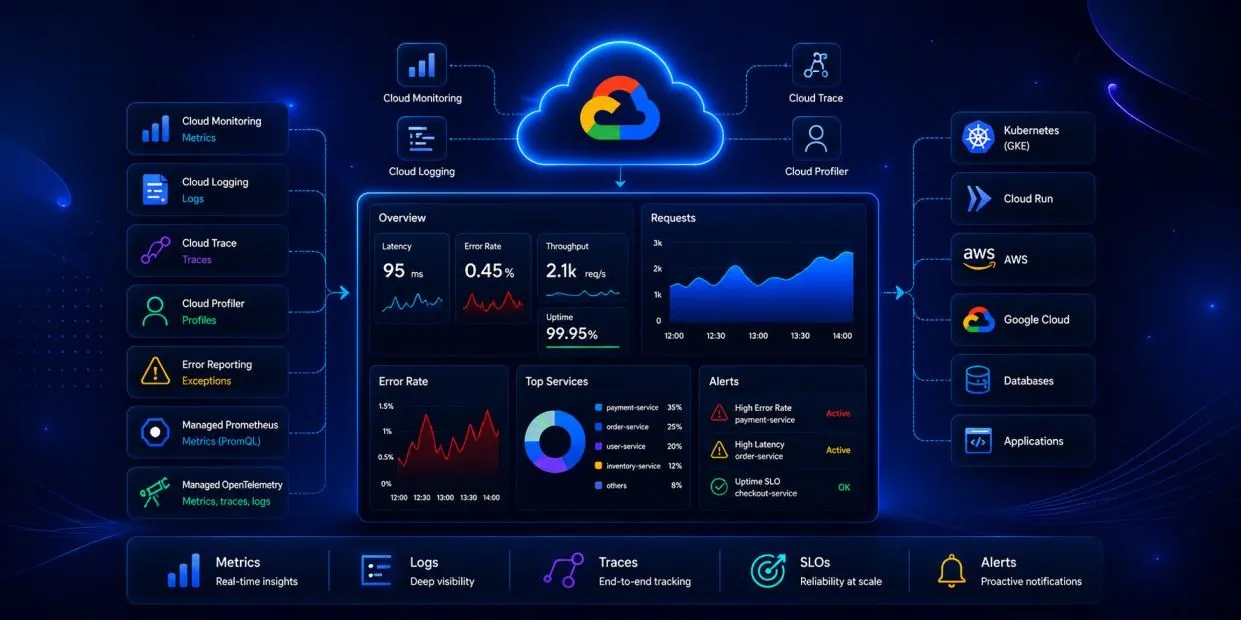
GCP Monitoring: A Complete Guide to Monitoring Google Cloud Applications and Infrastructure
A field guide to Google Cloud Monitoring, Cloud Logging, Cloud Trace, and the rest of the Google Cloud Operations Suite - what to instrument, how to alert without burning out your on-call rotation, and when native tooling stops being enough.
- ai observability
Introducing AI-Powered Incident Correlation & Root Cause Detection
An API latency spike triggers 40 alerts, none tell you the cause. Atatus Problems groups them into one AI-correlated incident with automatic root cause detection. See how it works.
- Observability
Observability: The Complete Guide (2026)
Observability means understanding why systems break, not just that they did. This guide covers logs, metrics, traces, OpenTelemetry, Kubernetes, and how to pick the right platform.
- Observability
Introducing Atatus MCP Server: Connect AI Agents to Your Observability Data
Atatus MCP Server bridges AI coding assistants like Claude and Cursor with your production observability data, letting agents query logs, traces, and metrics without leaving your editor.
- ai observability
How AI Is Transforming Production Issue Investigation for Modern DevOps Teams?
Stop losing hours to manual log searches. See how AI observability cuts MTTR by 60%, surfaces root causes in minutes, and keeps your production systems healthy.
- ai observability
Why Observability Is Essential for Platform Engineers?
Platform engineers can't scale when they're the first call for every incident. Learn how observability helps developers debug independently, reduces MTTR, improves onboarding, and supports SLO-driven reliability.
- ai observability
AI SRE Agent: How Autonomous Incident Investigation Is Eliminating Manual Root Cause Analysis
A P1 incident in Kubernetes requires correlating 47,000+ logs, 12 traces, and 8 service dependencies. Humans take 60–90 minutes. AI SRE Agents do it in 28 seconds. Learn how autonomous incident investigation is changing SRE workflows.