- ai observability
Why Observability Is Essential for Platform Engineers?
Platform engineers can't scale when they're the first call for every incident. Learn how observability helps developers debug independently, reduces MTTR, improves onboarding, and supports SLO-driven reliability.
- ai observability
AI SRE Agent: How Autonomous Incident Investigation Is Eliminating Manual Root Cause Analysis
A P1 incident in Kubernetes requires correlating 47,000+ logs, 12 traces, and 8 service dependencies. Humans take 60–90 minutes. AI SRE Agents do it in 28 seconds. Learn how autonomous incident investigation is changing SRE workflows.
- Observability
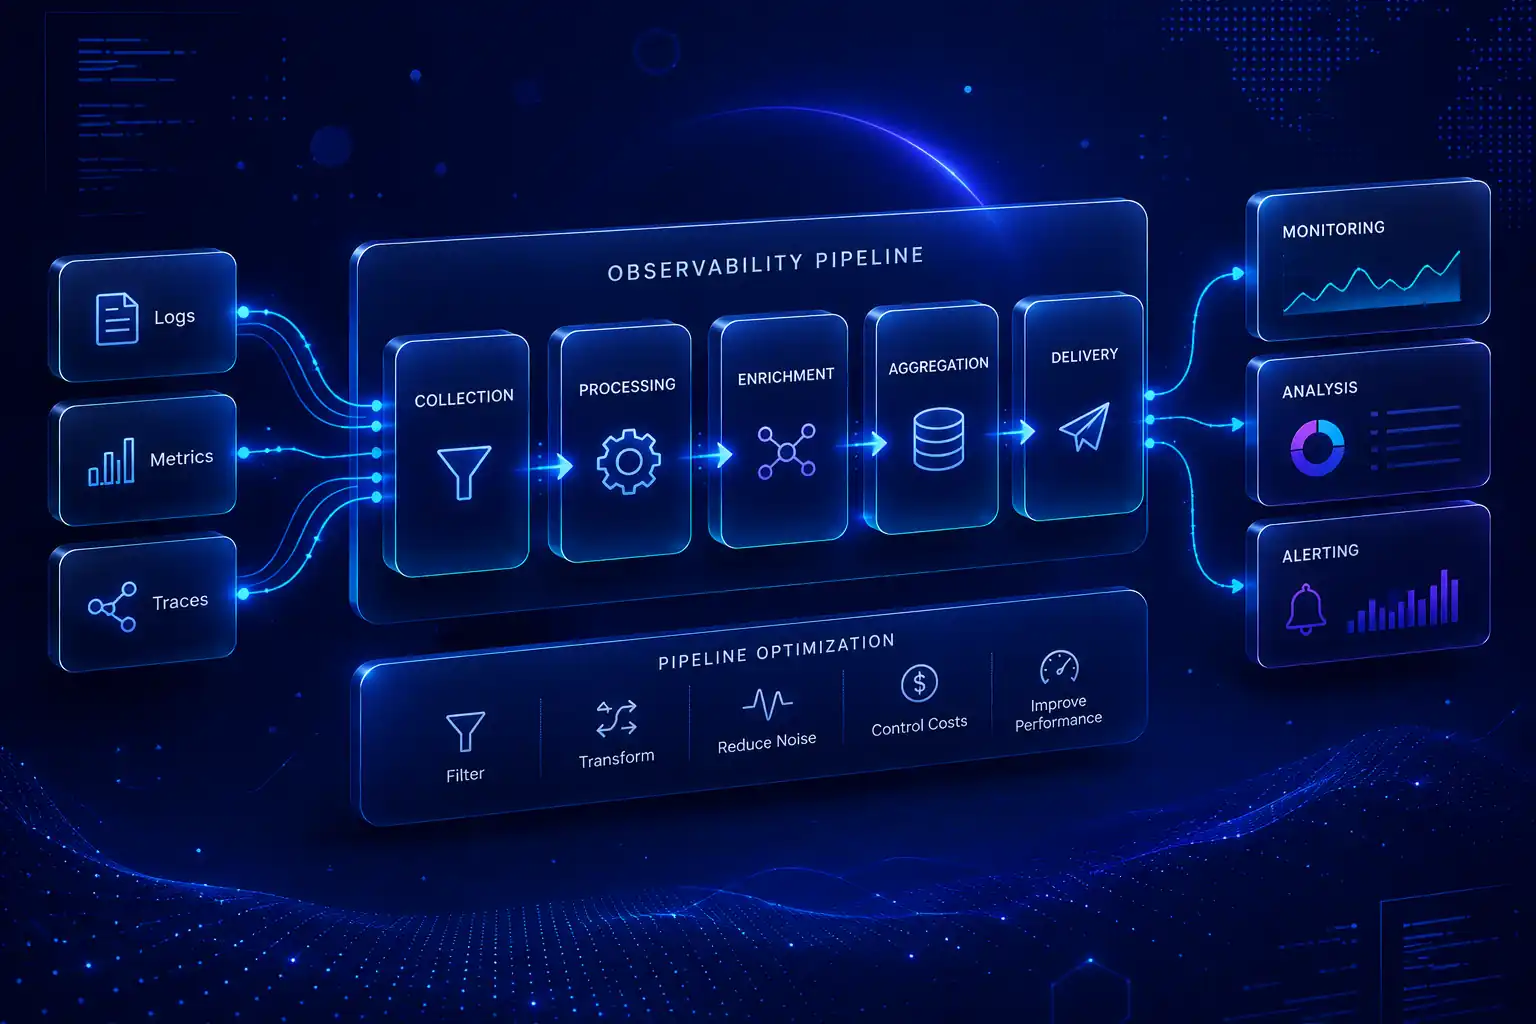
The Complete Guide to Observability Pipelines
Learn how observability pipelines work, how to reduce telemetry costs, and how to build scalable pipelines for logs, metrics, and traces. Start optimizing with Atatus.
- application security
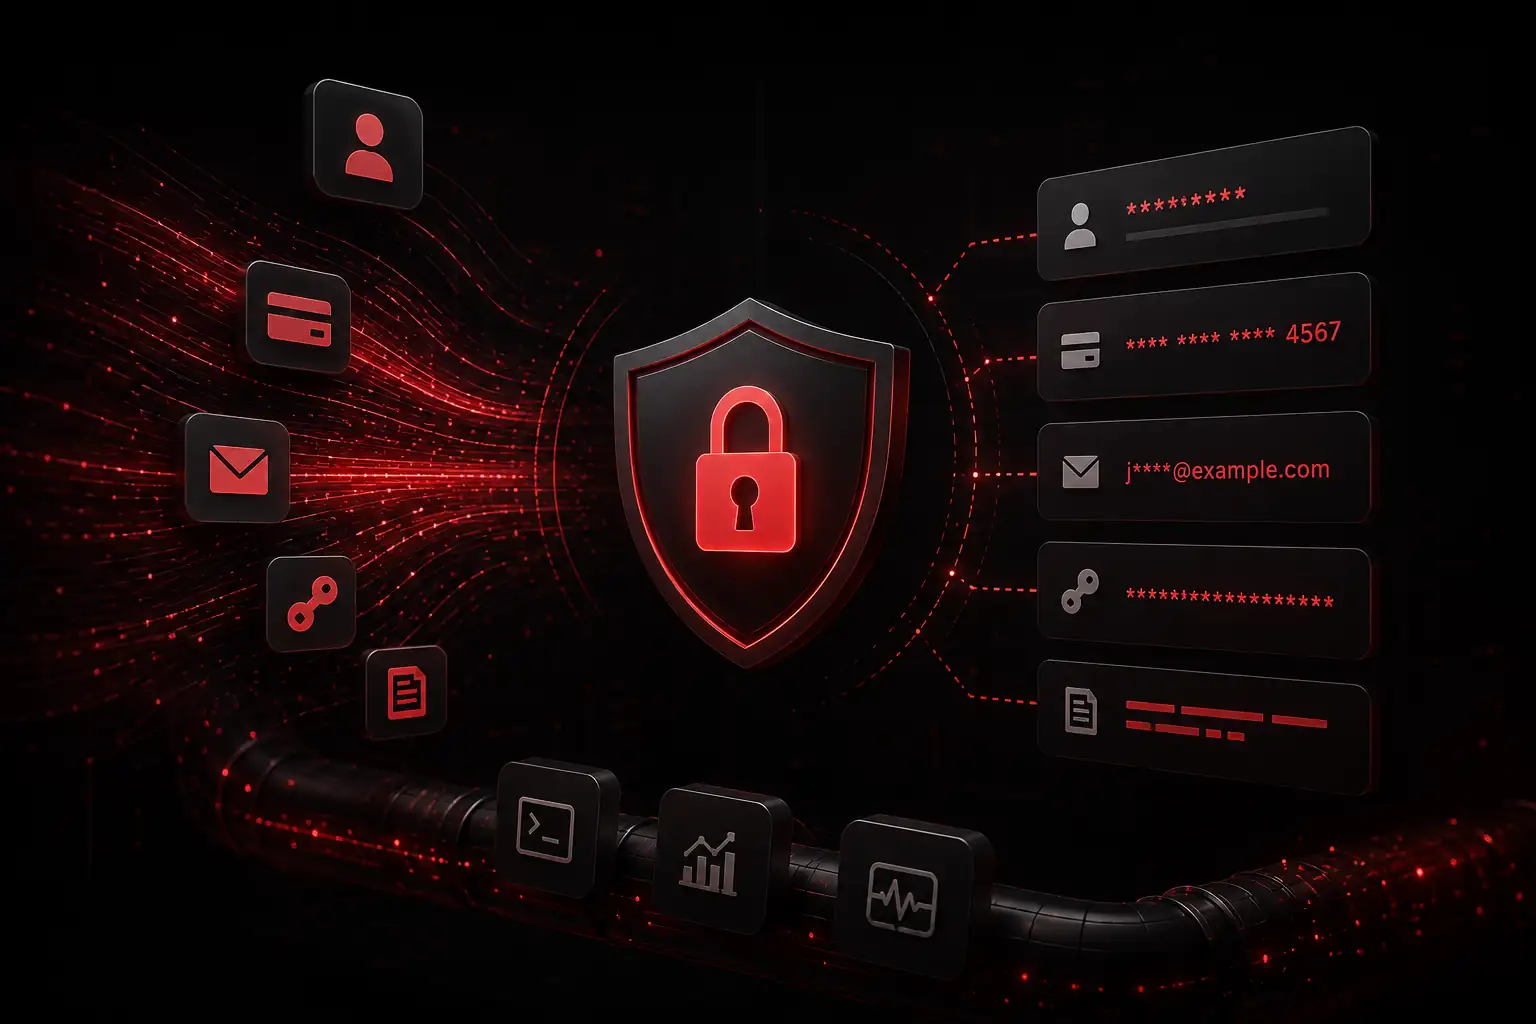
Introducing Atatus Sensitive Data Classifier
Sensitive data is hiding in your logs right now, including PII, API keys, JWT tokens, credit cards. Atatus Sensitive Data Classifier detects and redacts it automatically at ingestion, before it ever hits storage. Start your free trial today.
- alerts
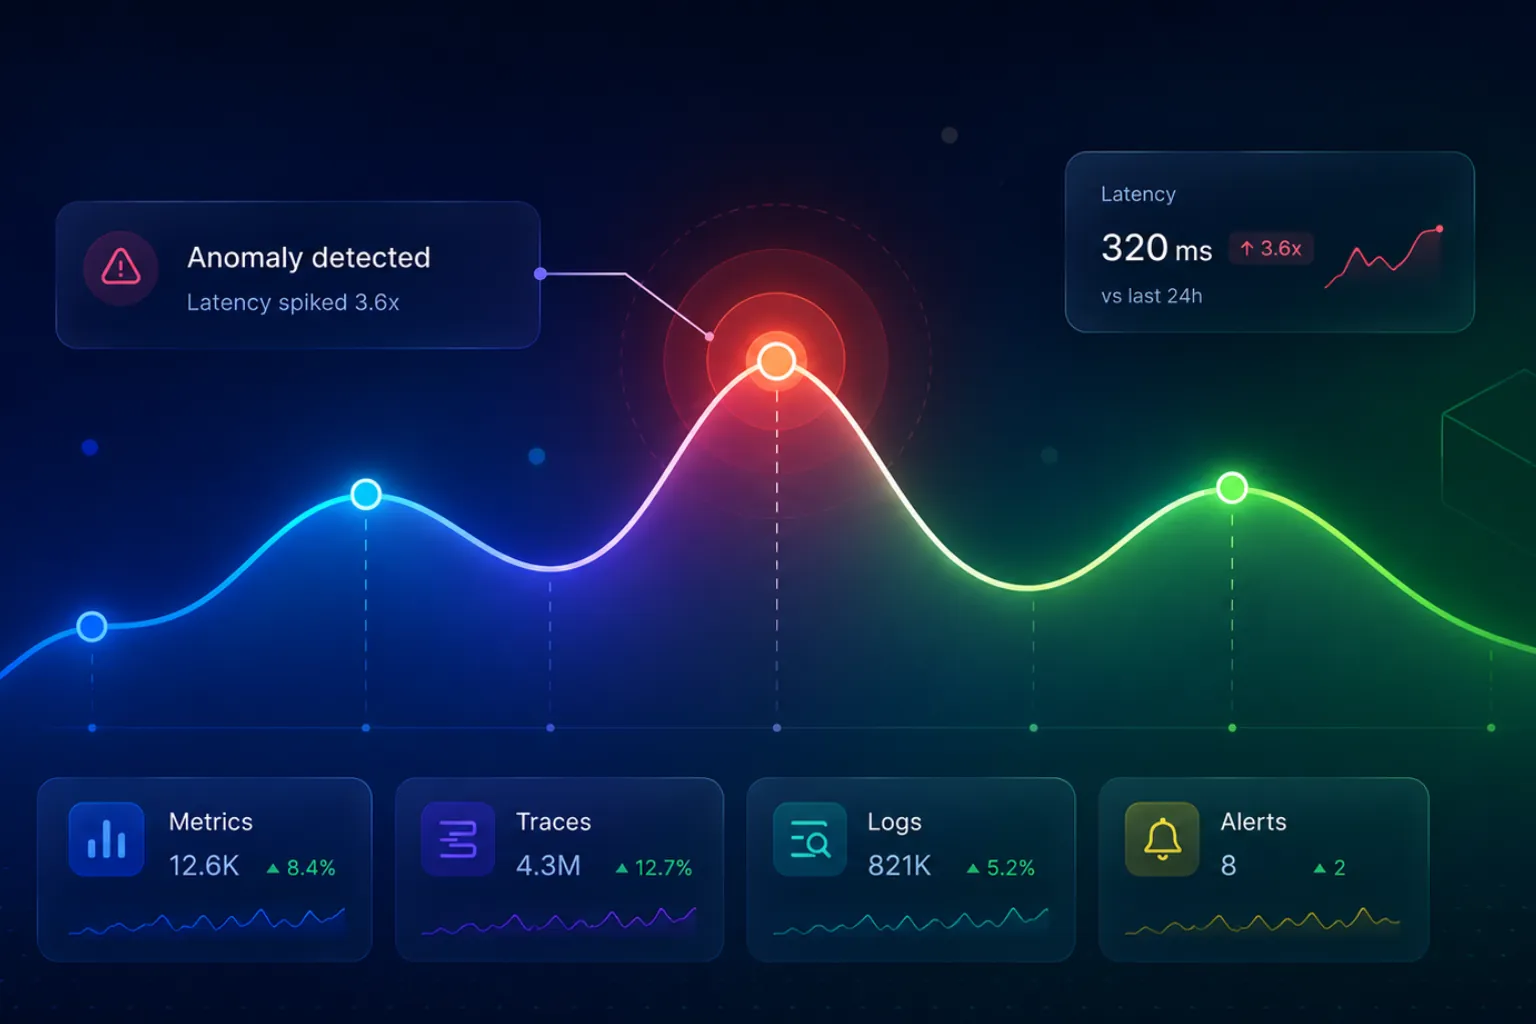
AI- Powered Anomaly Detection in Observability
Static thresholds miss what matters. Learn how anomaly detection in observability automatically surfaces real issues across logs, metrics, and traces before your users notice anything is wrong.
- Rabbitmq Metrics
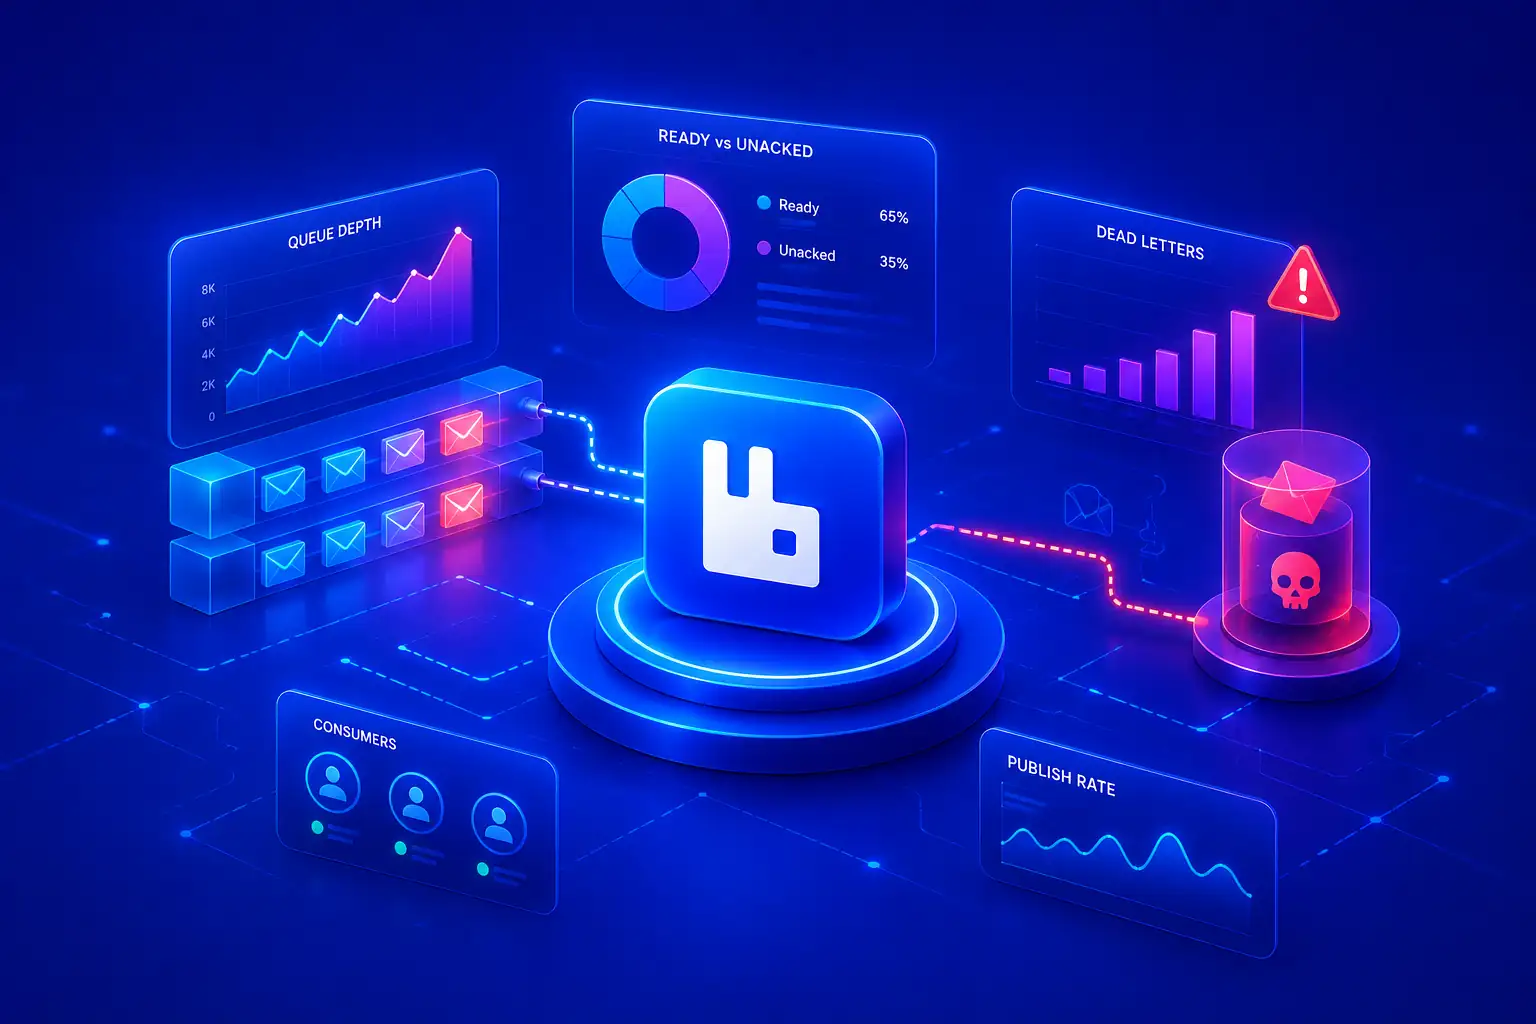
RabbitMQ Monitoring: Queue Depth, Dead Letters, and Common Failure Patterns
A production guide to RabbitMQ monitoring covering queue depth, ready vs. unacked messages, dead-letter causes, 10 real failure patterns, alerting strategy, and a step-by-step troubleshooting workflow.
- Observability
Improve Observability in Your CI/CD Pipeline
Learn how to monitor, secure, and optimize your CI/CD pipeline with observability. Deliver faster, reliable software while detecting issues early with Atatus.
- cardinality
Understanding High Cardinality and Its Role in Observability
High cardinality shapes how modern observability systems store and query data. Learn what it means, why cloud-native systems create so much of it, and how to manage it without losing visibility.
- Observability
Logging, Traces, and Metrics: What is the difference?
Metrics tell you what broke, logs tell you why, traces tell you where. A practical guide to the three pillars of observability, with real incident examples and OpenTelemetry.